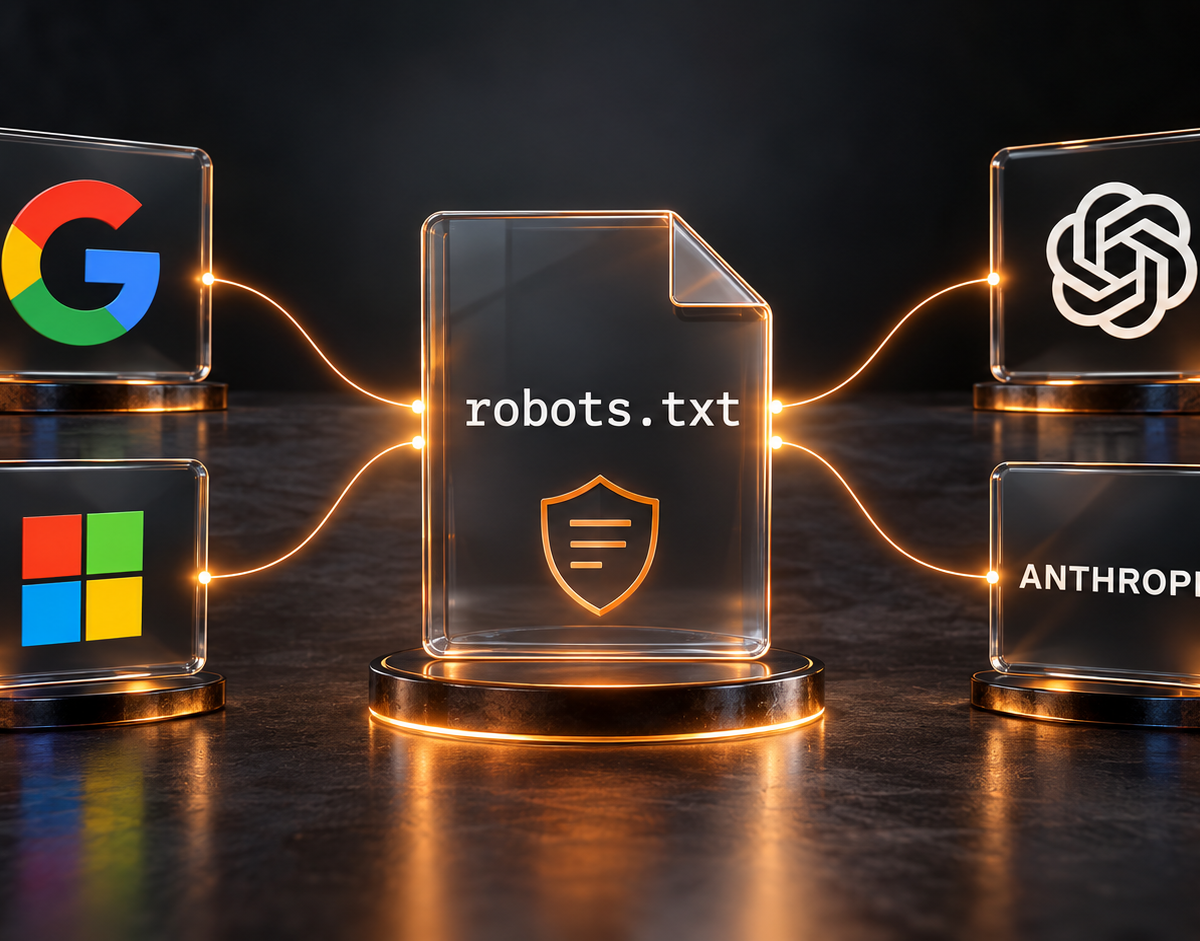
Google, Microsoft, OpenAI and Anthropic said on Friday (Oct. 30) they will honor a shared signal, placed in a website's robots.txt file, that lets site owners say whether their content may be used to train generative artificial intelligence models. The mechanism is laid out in a proposal submitted to the IETF (Internet Engineering Task Force, the body that sets technical standards for the internet) by Kevin Kelley, Anthropic's technical lead for standards. With a single rule, identified by the token __usage_ai-training, a site can state its preference to all four companies at once. Adoption will be gradual: Microsoft starts applying the signal on Feb. 1, 2027, and Google plans to support it during 2027.
Today, publishers that want to keep their content out of AI training have to identify each crawler and write separate rules for each provider, such as OpenAI's GPTBot and Google's Google-Extended. Robots.txt is a text file at the root of a website that tells these bots what they may and may not access. The proposal, registered as draft-kelley-aipref-training-preference-signal-00, was introduced on the mailing list of the IETF's AIPREF working group, which focuses on preferences for how AI systems use content.
The document is an individual submission. According to the IETF's own record, it has not been endorsed by the body and has no formal standing as a standard, and it may change before it expires in May 2027. Amazon, Apple and Meta are not among the companies that have committed to honoring the signal.
What changes for businesses
For companies that publish content online, such as blogs, news sites, online stores with product descriptions and help centers, the change cuts the technical work of controlling how AI uses their text. A single block in robots.txt, with the new token and the folders that should not be used for training, is enough. The draft's example blocks an entire site except its press kit. The signal expresses a preference about how content is used, not an instruction for bots to stop visiting pages. Existing catch-all rules, such as "User-agent: *", do not count as stating a preference.
The issue to watch for marketing teams is visibility. Google said that if a site uses the new token to opt out of training without mentioning Google-Extended, it will treat the rule as a block on Google-Extended. Sites that allow that crawler can appear in answers in the Gemini app. Besides the training control, Microsoft created a separate preference for so-called grounding, when an AI answer draws on a live web page, and warns that restricting it reduces brand visibility in AI experiences. Microsoft says the new preferences do not change pages' eligibility for traditional Bing results; at Google, opting out of training also does not remove content from search.
Nor does the signal undo past collection: content the companies have already gathered stays with them. Microsoft says the preferences create no licensing or payment arrangements, and private agreements between sites and AI companies can override what is in robots.txt. OpenAI said the new signal will not replace the controls it already provides through robots.txt, such as GPTBot.
“This will help websites express their AI training preferences across multiple AI providers in a single step.”
— Google, in a statement on the new control
What to watch next
- Dec. 15, 2026: Bing Webmaster Tools opens temporary transition preferences for sites that currently use the NoArchive or NoCache tags.
- Feb. 1, 2027: Microsoft starts applying the new training and grounding preferences.
- March 1, 2027: NoArchive and NoCache stop counting as training and grounding preferences on Bing.
- 2027: Google plans to support the signal; OpenAI says it will implement it in the coming months; Anthropic has already started implementation, with no completion date.
- IETF: progress of the proposal, which may change, and whether other companies, such as Amazon, Apple and Meta, sign on.